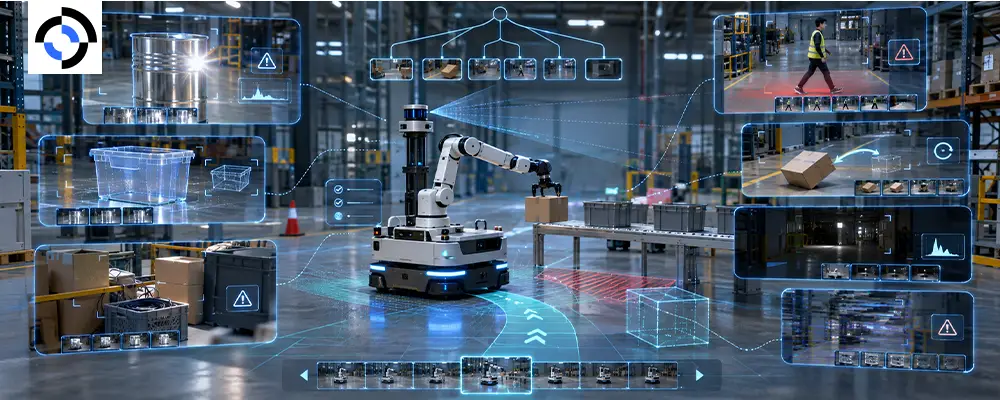
Most robots look great in the demo. The trouble starts in the field, where a reflective surface, an unusual object or a half-second sensor dropout appears once in a thousand attempts. Murphy’s Law, the old engineering adage that anything that can go wrong will go wrong, is not pessimism in robotics. It is a data requirement.
Edge-case data collection services exist to meet that requirement. This guide explains what counts as an edge case, why scheduled collection misses them, and how a robotics edge case data collection program is scoped, executed and measured.
What counts as an edge case in robotics
Edge cases are not simply hard tasks. They are conditions your policy rarely sees but will certainly meet.
- Rare objects: transparent, reflective, deformable or unusually shaped items
- Rare conditions: glare, low light, heavy occlusion and clutter
- Rare events: dropped objects, blocked paths, people stepping into the workspace
- Rare interactions: unusual grasp poses, tight tolerances, out-of-distribution instructions
Together these form the long tail. Rare event data for robotics is the evidence your model needs to handle it.
Why standard collection misses the long tail
Scheduled collection samples what you chose to collect, and people naturally choose common, convenient cases. A dataset can be enormous and still contain almost no tail. At scale the arithmetic is unforgiving: a policy that succeeds 99 percent of the time still fails once in every hundred attempts, which across thousands of daily tasks is a steady stream of stoppages. Long-tail robot data collection has to be deliberate, because it will not arrive by accident.
Our comparison of human demonstration and teleoperation data explains why fleet interventions are the one source that samples genuine failures rather than your guess at them.
How an edge-case collection program works
- Define the tail. Start from failure logs, support tickets and your intervention rate. Rank failure modes by cost, not by novelty.
- Mine what already exists. Fleet logs and intervention data contain real edge cases at no extra collection cost. Add structured fields so they become training input.
- Stage what is rare. Build scenarios on purpose: unusual objects, lighting changes, planned obstructions. Use data diversity scoring to confirm coverage.
- Use simulation where reality is unsafe. Simulation covers hazards that are costly or dangerous to stage, with the caveats in our post on sim-to-real limitations.
- Capture clean handling. Skilled operators demonstrate the correct response, working inside proper safety layers.
- Tag everything. Edge-case type, severity, trigger and resolution make the data searchable and balanceable.
Keep a representative set for evaluation
Oversampling the tail helps training but distorts measurement. Hold out edge-case episodes as a dedicated test split, separate from the broader distribution, and track success on it independently. Our guide to evaluating embodied AI policies covers split design in more depth.
Measuring whether it worked
A good edge-case program shows up in operations, not just in offline metrics. Track the intervention rate per thousand tasks, success on your dedicated tail benchmark, time to recovery after a failure and the volume of operator escalations. If those move in the right direction, the data is doing its job. If they do not, the tags will tell you which failure mode to collect next.
What to ask an edge-case data collection provider
- How do you identify edge cases: from logs, customer input or scenario design?
- Can you tag and report coverage by edge-case type?
- How do you stage rare events safely?
- Can you combine fleet intervention data with new teleoperation collection?
- How is the edge-case set kept separate for evaluation?
Where Roborax fits
Roborax’s long-tail and edge-case capture service pairs scenario design with dedicated operator teams and structured tagging, so rare cases arrive labeled and ready to train on. We work across warehouse, mobile manipulation, humanoid and surgical settings, and we plan collection against the failures that cost you most.
“The long tail is not a data volume problem. It is a data selection problem.” — Roborax data operations team
Frequently asked questions
Q: How many edge-case episodes do we need?
A: There is no universal number. Start with the failure modes that cost the most, collect enough varied episodes per mode to move your tail benchmark, and iterate based on results.
Q: Is simulation enough for edge cases?
A: No. Simulation is valuable for hazardous or expensive scenarios, but real-world capture is needed to close the gap on contact, lighting and sensor behavior.
Q: Should edge cases be mixed into the main training set?
A: Usually yes, with sensible weighting, as long as a separate edge-case split stays untouched for evaluation.
If your robot succeeds in the lab and struggles in the field, the tail is the place to look. Tell us what you are training and we will scope an edge-case collection program around your costliest failures.