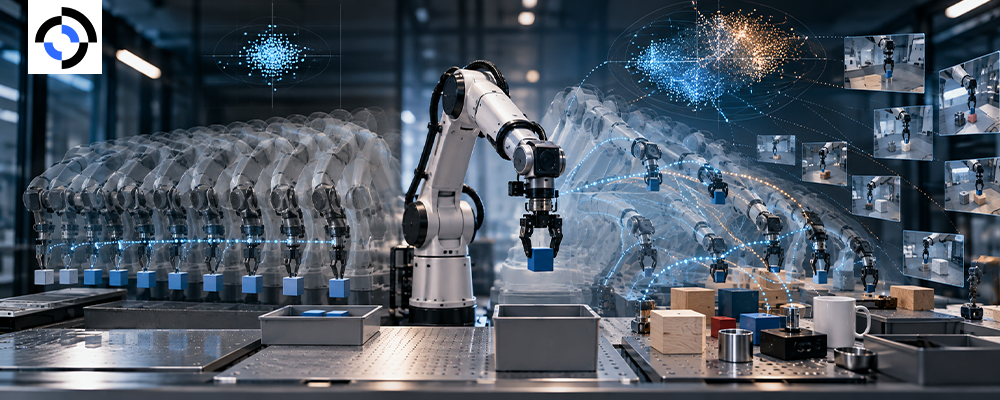
A robot can be trained on millions of demonstrations and still fail when it encounters something slightly different from what it has seen before.
A new object. A different camera angle. A changed workspace. An unfamiliar operator. A slippery surface. An unexpected obstruction.
For robotics teams building systems for real-world deployment, this exposes a critical problem: dataset size does not automatically equal dataset coverage.
The real question is: How diverse is your robot training data, and how much of the deployment environment does it actually represent?
This is where data diversity scoring becomes increasingly important. By systematically measuring variation across tasks, objects, environments, motions, sensors, operators, and edge cases, robotics teams can determine whether their datasets are genuinely preparing models for the physical world.
At Roborax, we see dataset diversity as an engineering requirement—not a checkbox in the data collection process.
This post covers why synchronization drifts, how to measure it, and what a properly synchronized capture rig looks like in production.
Why Dataset Diversity Matters in Robotics
Robotic learning takes place in an unusually complex environment. Unlike conventional machine learning systems that primarily process digital information, robots must interpret and act within changing physical environments.
A manipulation model may encounter the same object at different orientations. A humanoid may perform the same task with different body configurations. An autonomous system may experience different lighting, weather, surfaces, obstacles, and human behaviors.
This makes training data variety essential for generalization.
Research supports this principle. The BridgeData V2 dataset contains 60,096 trajectories across 24 environments and 13 skills, with variation in objects, camera positions, workspaces, and tasks. Its authors found that greater variety of skills improved generalization.
Similarly, RoboNet was created with approximately 15 million video frames from seven different robot platforms, specifically to investigate whether robot-learning systems could generalize across new objects, tasks, scenes, camera viewpoints, grippers, and robots.
The lesson is straightforward:
A robot dataset should represent the variability a robot is expected to encounter—not simply the volume of demonstrations that can be collected.
What Is Data Diversity Scoring?
Data diversity scoring is a systematic approach to quantifying how broadly a dataset represents relevant operating conditions.
Instead of evaluating a dataset only by its number of images, videos, trajectories, or demonstrations, teams measure coverage across multiple dimensions.
A robotics dataset may be scored across:
- Task diversity: Different tasks, subtasks, goals, and action sequences
- Object diversity: Shapes, sizes, materials, colors, weights, and states
- Environmental diversity: Workspaces, facilities, layouts, surfaces, and backgrounds
- Motion diversity: Different trajectories, speeds, joint configurations, and manipulation strategies
- Sensor diversity: RGB, depth, LiDAR, tactile, audio, proprioceptive, and other modalities
- Human diversity: Different operators and interaction patterns
- Condition diversity: Lighting, clutter, occlusion, noise, weather, and visibility
- Failure diversity: Slips, collisions, failed grasps, interruptions, and recovery behaviors
A dataset with high scores across these dimensions is more likely to expose a model to the variability required for robust deployment.
Building a Dataset Coverage Analysis Framework
A meaningful dataset coverage analysis begins with the robot’s intended deployment environment.
For example, consider a warehouse robot responsible for picking packages.
Its dataset should not simply contain thousands of successful pick-and-place demonstrations. It should capture different package sizes, materials, orientations, bin positions, lighting conditions, occlusion levels, grasp strategies, and failure scenarios.
Robotics teams can construct a coverage matrix:
| Dataset Dimension | Example Coverage Target |
|---|---|
| Object categories | 90%+ of deployment classes |
| Object orientations | Multiple orientations per class |
| Workspace zones | All operational zones |
| Lighting | Normal, low, high, variable |
| Operators | Multiple operators |
| Motion strategies | Multiple successful trajectories |
| Failure cases | Defined edge-case threshold |
| Sensor configurations | All deployment configurations |
The exact thresholds will vary by application, but the methodology remains the same: define the deployment distribution first, then measure how well the dataset represents it.
Key Data Diversity Metrics Robotics Teams Can Track
There is no single metric capable of describing every dimension of robotic data diversity. Instead, organizations can combine several data diversity metrics robotics teams can use for practical evaluation.
1. Category Coverage
Category coverage measures how many required categories are represented.
For example:
Coverage = Represented Categories ÷ Required Categories × 100
If a robot is expected to interact with 100 object categories but training data contains only 65, the dataset has a significant coverage gap.
2. Distribution Balance
Coverage alone is insufficient.
Suppose a dataset contains 100 object categories, but 80% of demonstrations involve only five objects. Technically, all categories are present—but the distribution is heavily imbalanced.
Distribution analysis identifies whether frequently occurring categories are overwhelming rare but important scenarios.
3. Entropy-Based Diversity
Entropy can provide a statistical measure of how broadly observations are distributed.
A 2026 robotics study proposed a model-free diversity metric based on entropy and demonstrated that diversity-aware demonstration selection consistently improved downstream success rates compared with random selection across simulated and real-world manipulation tasks.
This is particularly valuable when teams need to reduce a massive dataset while preserving its most informative demonstrations.
4. Embedding-Space Coverage
High-dimensional embeddings can help identify redundancy.
If thousands of trajectories occupy a very small region of an embedding space, the dataset may contain substantial duplication in terms of behavior or visual conditions.
Conversely, sparsely populated regions may represent underexplored behaviors or environments worth collecting.
Why Dataset Size Can Be Misleading
Imagine two robotics datasets.
Dataset A: 500,000 demonstrations from one facility, two operators, three object categories, and consistent lighting.
Dataset B: 150,000 demonstrations covering multiple operators, facilities, objects, lighting conditions, task variations, sensor configurations, and failure scenarios.
First one is larger.
While the second one may be significantly more valuable for generalization.
This is precisely why robot dataset evaluation must move beyond counting samples.
The 2026 study on diversity-aware robot dataset curation reinforces this idea: intelligently selecting diverse demonstrations can produce better downstream results than simply selecting random subsets of the same data.
As robotics datasets grow, the objective should therefore become:
More useful variation—not merely more data.
Measuring Motion Diversity
One of the most overlooked aspects of robotics data is motion diversity.
Two demonstrations may involve the same object and task but use completely different trajectories.
For example, a robot may grasp a cup from the front in one demonstration and approach it from the side in another. Both examples may be equally valid, but they expose the policy to different action distributions.
Recent CVPR 2026 workshop research specifically examined motion diversity in community-collected VLA datasets. The researchers introduced HeteroMotion, containing 1,050 trajectories across 15 tasks and five behavior categories, and reported broader motion coverage across robot joints alongside improved downstream real-world performance.
This demonstrates why diversity scoring should evaluate how robots move, not only what they see.
From Dataset Scoring to Better Robot Training
Data diversity scoring becomes most valuable when it influences collection decisions.
A robotics team can use diversity analysis to identify:
- Missing object categories
- Underrepresented environments
- Repetitive trajectories
- Rare failure modes
- Sensor gaps
- Operator biases
- Underrepresented motions
- Excessive concentration around successful demonstrations
The result is a more intelligent data collection loop:
Collect → Measure → Identify Gaps → Rebalance → Validate → Collect Again
This approach prevents teams from spending resources collecting thousands of additional examples that provide little incremental information.
How Roborax Helps Build More Representative Robotics Datasets
At Roborax, we approach robotics data collection with the understanding that physical AI models need more than clean demonstrations. They need variation, context, edge cases, and realistic interaction patterns.
Our robotics data solutions can support datasets spanning manipulation, humanoid robotics, autonomous systems, warehouse environments, teleoperation, sensor data, and Physical AI applications.
From defining collection requirements to capturing diverse demonstrations and structuring data for downstream training, Roborax helps robotics teams build datasets around the realities of deployment.
The objective is not simply to deliver a larger dataset.
It is to deliver a dataset that teaches robots how the real world varies.
Conclusion: Measure Coverage Before You Scale
The future of robotics will not be determined solely by model architecture or compute. High-performing robots also require training datasets capable of representing the complexity of real-world environments.
That means dataset teams need to ask better questions:
- Which situations are represented?
- Which are missing?
- Which behaviors are overrepresented?
- And how much diversity is enough for deployment?
Data diversity scoring provides a practical framework for answering those questions.
By combining category coverage, distribution analysis, entropy, embedding-space analysis, motion diversity, and deployment-oriented validation, robotics teams can transform dataset evaluation from a simple quality check into a strategic part of model development.
At Roborax, we help robotics innovators move from data volume to data intelligence—building training datasets designed for stronger generalization and real-world Physical AI performance.
Ready to measure whether your robot dataset is truly deployment-ready?
Talk to Roborax
Connect with Roborax to explore robotics data collection, teleoperation, annotation, dataset curation, and Physical AI training-data solutions tailored to your robot, task, and deployment environment.
Frequently asked questions
Q: Is more diversity always better?
A: Generally yes for generalization, but diversity should be relevant to your actual deployment distribution — maximizing diversity on dimensions your robot will never encounter in production wastes collection budget that could go toward relevant variation.
Q: How does diversity scoring relate to long-tail data collection?
A: They’re closely related — diversity scoring is often how a team discovers which long-tail scenarios are underrepresented in the first place, turning a vague sense of “we need more edge cases” into a specific, measurable gap.
Q: Can diversity scoring replace real-world evaluation?
A: No. It’s a strong proxy for likely generalization but doesn’t replace measuring actual policy performance on real, held-out scenarios.
If you don’t know how diverse your current dataset actually is, that’s usually the first gap worth closing.Talk to Roborax about measuring and closing your coverage gaps.
- Related reading
External reference