Depth Camera Calibration Best Practices for Data Teams
For robots operating in the physical world, seeing an object is only the beginning. A robot must also understand how far away it is, where
Home / Data services / Annotation and labeling
Action segmentation, affordance masks, language captions, reward signals — at the bar your model deserves.
Annotation and labeling is the process of adding structured metadata to raw robotics data — action boundaries, affordance masks, natural-language captions, and reward signals — so your model knows what happened, where, and why it mattered.
Labeling robotics data requires domain expertise, not just clicking boxes. Our annotators are trained on manipulation, locomotion, and navigation tasks.
Why outsource labeling?
Your engineers should be iterating on architectures, not drawing masks. We scale annotation teams up and down to match your training cycles.
1,200 labels/hr per trained annotator.
48-hour turnaround on standard batches.
14 modalities supported out of the box.
Where we collect
41+ delivery centers across 12 countries. Every program runs from a Roborax hub near your target time zone.
Asia Pacific
India · Philippines
Americas
USA · Canada · Colombia · Jamaica · El Salvador · Belize
EMEA
UK · Albania · Kosovo · Morocco
Four label types that bridge raw capture to a training-ready dataset.
Frame-level action labels with start, end, and class for every clip.
Pixel-level masks of graspable, pushable, and contact regions.
Free-form and templated natural-language descriptions per scene.
Dense or sparse reward per timestep for RL and IRL pipelines.
Four stages that lock the bar before billable work and verify it after.
Acceptance criteria locked with your team. Edge cases documented in writing.
Operators pass a gold-set bar before producing billable labels.
Production labeling with daily QA review and same-day rejections.
Held-out 5% sample re-reviewed by seniors. Accuracy report per batch.
Use ours, use yours, or use the open-source standard.
OSS, self-host
Enterprise SaaS
Enterprise SaaS
Multi-modal
Lightweight
Your pipeline
FAQ
COCO, CVAT, YOLO, custom JSON, ROS bag with annotation overlays, and RLDS for trajectory data. If you use an internal format, share the schema and we will build a converter.
Our baseline is 99.4% label accuracy across active programs. We achieve this through multi-pass review, consensus labeling on ambiguous frames, and a dedicated QA team that audits every batch before delivery.
Every label goes through automated validation checks, a human review pass, and a final QA audit. Batches that do not meet your agreed accuracy threshold are re-labeled at no additional cost.
Yes. Send us your label taxonomy, class definitions, and any edge-case guidance before the program starts. We build that into operator training and validation tooling.
Ambiguous frames are flagged in the delivery manifest with a confidence score. You choose whether to include them in training, discard them, or send them back for adjudication.
From the blog
Robot Data Annotation: A Practical Guide for ML TeamsRubrics, workflows, and QA standards for robot annotation programs.
From the blog
The QA Pipeline Every Robotics Data Team NeedsHow to build quality assurance into your annotation pipeline.
Send us a sample batch and the spec. We come back with a calibrated quote in three days.
FROM THE FIELD

For robots operating in the physical world, seeing an object is only the beginning. A robot must also understand how far away it is, where

What a wearable capture rig must carry, why field logistics stall programmes more than engineering does, consent in shared spaces, and quality controls that work.
A robot may have excellent sensors, sophisticated actuators, and a powerful learning model—but if the data used to train that robot is poorly synchronized, the
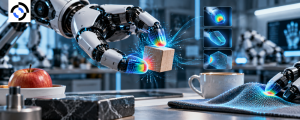
A robot can see an object without understanding how it feels. A camera can identify a cup, estimate its position, and guide a robotic hand
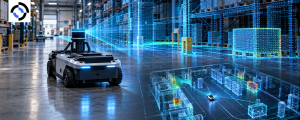
A mobile robot cannot navigate a warehouse, factory, hospital, or outdoor environment from camera images alone. It needs to understand distance, geometry, obstacles, surfaces, and
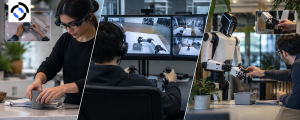
Human demonstration and teleoperation produce different action labels with different traps. Plus the third category, intervention data, that most teams never budget for.
Seven services. One synchronized pipeline.
VR and leader-follower robot control logging.
In-person task demos for imitation learning.
RGB-D, LiDAR, force, and tactile streams.
Domain-randomized scenes and sim transfers.
Held-out test sets and success-rate scoring.
Rare scenarios your policy will face in production.