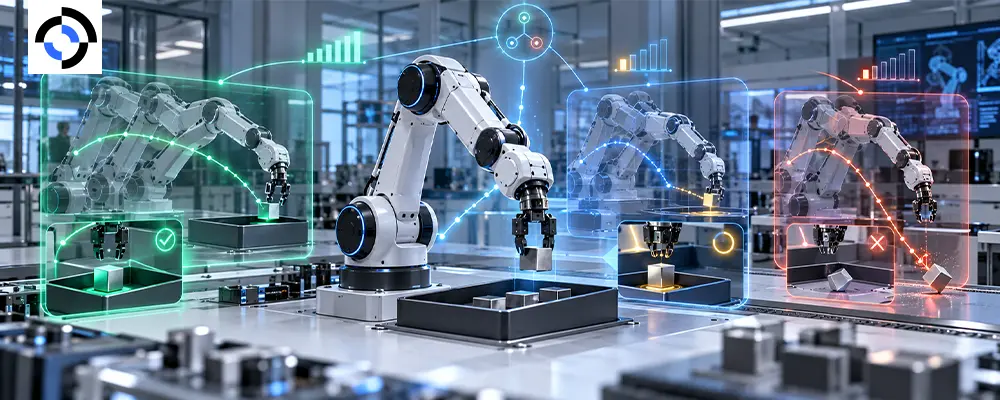
Behavior cloning treats every demonstration as equally good. Reinforcement learning cannot afford to, because it needs to know what worked. Robot outcome labeling supplies that signal by attaching success, failure and reward information to each trajectory.
This guide explains how to design success failure annotation, when reward labeling is worth the cost, and how trajectory quality labels turn mixed-quality logs into usable offline reinforcement learning data.
Demonstration datasets teach imitation. Add outcomes and you unlock much more: filtering to successful episodes, weighting good behavior higher, learning from failures, and training a value function or reward model. Intervention and fleet logs are especially rich here, because they hold plenty of failures that pure imitation would throw away.
Sergey Levine and colleagues described the promise of offline RL as the ability to “turn large datasets into powerful decision making engines.” That only works if the dataset records which outcomes were good.
Three layers of outcome labels
| Label | Form | Annotation cost | Best for |
| Success or failure | Binary or graded, per episode or segment | Low | Filtering, evaluation, classifiers |
| Reward | Scalar per step or per segment | High | Reinforcement learning, reward models |
| Trajectory quality | Ordinal grade or pairwise ranking | Medium | Weighted imitation, preference learning |
Start with success and failure. Most of the practical value comes from that first layer, and the other two build on it.
Define success so annotators agree
“Did it work?” is not a labeling instruction. Write success criteria as checks an annotator can verify from the recording:
- Goal state: the object is inside the bin and not resting on the rim
- Stability: the object stays in place for a defined hold period
- Safety: no collision and no dropped item mid-transfer
- Time limit: the task completes within a set horizon
Support binary labels with graded ones (success, partial success, failure) and a failure mode taxonomy such as missed grasp, slip, collision, wrong object and timeout. A taxonomy converts a pile of failed episodes into a debugging map.
Reward labeling without the traps
Sparse reward, one at success and zero otherwise, is cheap and unambiguous but gives little signal on long tasks. Dense reward gives guidance and invites reward hacking, where a policy optimizes the proxy instead of the goal. A practical middle path:
- Label milestones. Mark sub-task completion, building on task segmentation for long-horizon demonstrations.
- Derive step-level reward automatically from milestones rather than hand-scoring every frame.
- Collect preference labels. Annotators compare two trajectories and pick the better one. Ranking is easier and more consistent than assigning absolute scores, and it trains a reward model.
Audit the reward. Check that it ranks known-good episodes above known-bad ones before any policy trains on it.
Trajectory quality labels in mixed-source data
Real datasets mix expert demonstrations, novice attempts, interventions and autonomous rollouts. Tag the source and a quality grade covering smoothness, efficiency, hesitations and recoveries, so training can weight each appropriately.
Keep the origin metadata. An autonomous failure and an operator error can look identical in an outcome label but need different treatment. Our posts on the intervention data training loop and robot fleet intervention rate show how fleet logs become labeled outcomes. For the wider strategy, see from imitation learning to RL.
Pitfalls that quietly damage outcome data
- Survivorship bias. Dropping failures removes the negative examples RL needs.
- Label leakage. Judging steps after watching the ending biases step-level labels, so label milestones in order.
- Shifting criteria. Version your success definition. Changing it mid-project silently relabels history.
- Ignoring partial success. Binary labels throw away most of the information in near-misses.
At Roborax, outcome labeling runs through the same review pipeline as the rest of our annotation and labeling work, with success criteria agreed before the first episode is labeled.
Frequently asked questions
Q: Do we need reward labels for imitation learning?
A: No. Imitation needs success filtering at most. Reward labels matter when you move to offline RL, value learning or reward-model-based fine-tuning.
Q: Binary or graded success?
A: Record graded outcomes and derive binary labels from them. You can always collapse labels later, but you can never expand them.
Q: Should humans or models label outcomes?
A: Both. Automated checks verify measurable conditions such as goal position, while humans judge ambiguous cases and preferences. Sample the automatic labels for human audit.
Policies learn from what you reward and what you filter out. If you are planning outcome labels for an existing dataset or a new collection program, tell us what you are training and we will design the success criteria and failure taxonomy with you.