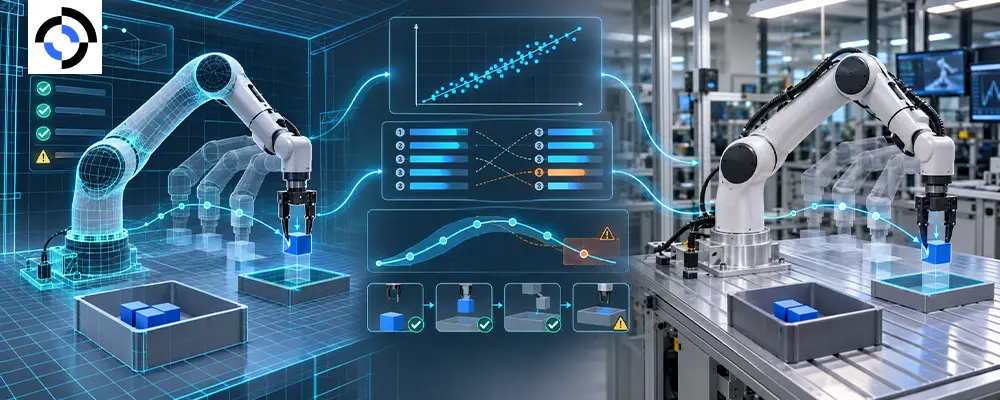
Simulation is the only way to evaluate hundreds of checkpoints overnight. It is also a measuring instrument that may or may not agree with reality. Sim-to-real evaluation correlation is the test: when a policy scores higher in simulation, does it also score higher on the real robot?
This guide covers how to measure that correlation, what makes simulation benchmarks valid or misleading, and how to use simulation for screening without trusting it for the final call.
Why correlation, not absolute score, is the right test
A simulator can be wrong about absolute success rate and still be useful, as long as it ranks policies correctly. For checkpoint selection and ablations, ranking is what you need. George Box’s line applies to every simulated benchmark: “All models are wrong, but some are useful.” The question is whether yours is useful for the decision in front of you, and that is an empirical question you can measure.
How to measure sim-to-real evaluation correlation
- Pick a spread of policies. Use eight to ten checkpoints or variants spanning low to high performance. A narrow range hides correlation.
- Evaluate them on real hardware with a proper protocol and confidence intervals, as described in our robot policy evaluation protocol.
- Evaluate the same policies in simulation on matched tasks.
- Compute agreement. Pearson correlation captures linear agreement and Spearman captures rank agreement. Work such as SIMPLER also uses mean maximum rank violation, which measures how badly simulation misorders policies.
- Bootstrap an interval. With few policies, a high correlation can be luck, so report its uncertainty.
- Re-validate when anything changes: a new simulator version, scene or controller.
What drives agreement
| Factor | What to match | If mismatched |
| Visual appearance | Textures, lighting, camera pose, background | Perception-driven failures differ |
| Control | Action space, controller gains, latency | The same commands produce different behavior |
| Physics | Friction, mass, contact model | Contact-rich tasks diverge |
| Task definition | Success criteria, initial states, object set | Different tasks under the same name |
| Training data | Whether the policy trained in the benchmark scene | Leakage inflates simulation scores |
For vision-based manipulation policies, control and visual matching tend to matter most, while physics matters more as tasks become contact-rich. Rebuilding the real evaluation scene in simulation helps the visual side, which is why digital twins built from real scans are increasingly used for evaluation as well as training.
Where simulated benchmarks mislead
- Training-distribution leakage. If a policy trained on simulated data from the benchmark scene, simulation scores measure memorization.
- Contact and deformables. Cloth, cables, liquids and soft contact are exactly where simulators are weakest.
- Saturation. When most policies score near 100 percent, simulation cannot discriminate between them.
- Narrow task sets. A benchmark of five tasks may correlate on those five and say nothing about the sixth.
- Hidden defaults. Physics engine versions and solver settings change outcomes silently, so pin them.
A practical workflow
Use simulation as a funnel. Screen many checkpoints in simulation, advance the top candidates to a small real evaluation, and make release decisions on real results only. Log both numbers for every checkpoint. After a few cycles you hold a calibration record of how much trust your simulator has earned.
When correlation drops, treat it as a bug in the benchmark, not in reality. Roborax pairs real evaluation collection with our synthetic and sim-to-real work so the two sides can be calibrated against each other. For the limits of the synthetic side, see sim-to-real transfer and synthetic data limitations.
Frequently asked questions
Q: What correlation is good enough?
A: There is no universal threshold. The goal is rank agreement strong enough to pick the right checkpoint reliably. With few policies, report an interval rather than a single coefficient.
Q: Can simulation replace real evaluation?
A: Not for release decisions. It screens candidates and speeds iteration, while real trials remain the ground truth.
Q: How often should we re-check the correlation?
A: Whenever the simulator, scene, controller or task definition changes, and on a regular cadence otherwise.
A simulated benchmark is a hypothesis about reality, and a small set of real trials is how you test it. If you want help designing the real validation set, tell us what you are training and we will scope it with you.