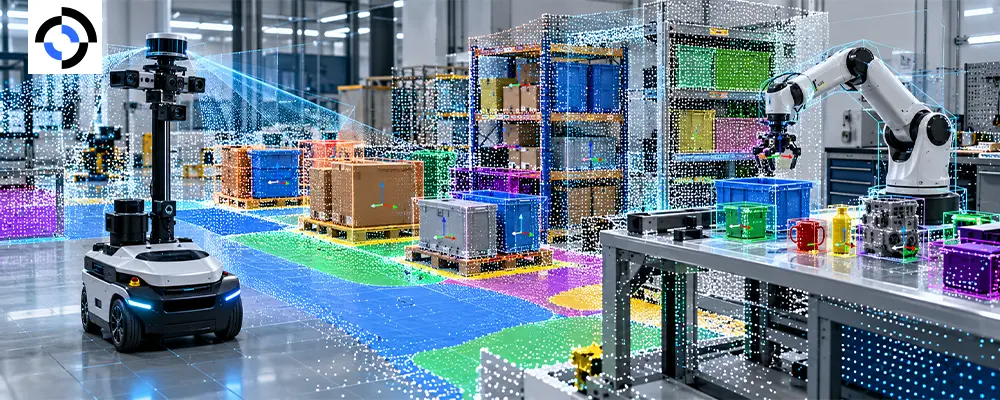
A camera tells a robot what something looks like. A point cloud tells it where things are. For navigation, grasp planning and obstacle avoidance, that geometry is what the perception stack actually acts on, which makes point cloud annotation one of the most consequential jobs in robot perception data.
This guide covers the main 3D label types, how 3D bounding box labeling differs from semantic segmentation robotics tasks, what makes LiDAR annotation services hard, and the QA that keeps 3D labels trustworthy.
Why point clouds need their own annotation approach
Point clouds are sparse, unordered and view-dependent. Density falls with distance, surfaces vanish behind occlusions, and reflective or transparent materials return noise. Annotators cannot lean on the visual cues they use for images, so tooling and guidelines both have to change.
The classic reference point is PointNet, whose authors opened with a plain observation: “Point cloud is an important type of geometric data structure.” Since then, 3D perception has become central to mobile manipulation and autonomous navigation, and the labels behind it have become a bottleneck.
Core label types
| Label | Output | Used for | Relative cost |
| 3D bounding box | 7-DoF cuboid: x, y, z, length, width, height, yaw | Detection, tracking, obstacle avoidance | Medium |
| Semantic segmentation | A class for every point | Scene understanding, traversability | High |
| Instance segmentation | Class plus object ID per point | Picking individual objects, manipulation | High |
| Object pose or keypoints | 6-DoF pose or part keypoints | Grasp planning, assembly | High |
| Tracking IDs | Persistent IDs across frames | Dynamic scenes, motion prediction | Medium to high |
Pick the cheapest label that supports the decision your robot makes. A warehouse AMR may need boxes and a drivable-surface mask. A bin-picking arm needs instance masks and object pose.
3D bounding box labeling: where consistency breaks
Boxes look simple and drift constantly. Write explicit rules for:
- Tightness: the box encloses all returned points of the object, with a stated margin.
- Orientation: yaw is defined from the object’s front, not from its direction of travel.
- Occlusion: partially visible objects are boxed to their estimated full extent and carry an occlusion flag.
- Sparse objects: set a minimum point count below which an object is marked ignore rather than background.
- Ground contact: define how ground points are handled so surface returns are not swept into the box.
Semantic segmentation for robotics
Per-point labels are the most expensive and the most useful. Robotics ontologies differ from driving ontologies. You care about graspable objects, shelves, doors, handles, floor types and nearby people, not lane markings.
Keep the class list short enough to apply consistently, include an explicit “unknown” class, and define boundary behavior where classes meet, such as a mug resting on a table. Model-assisted pre-labeling helps: a segmentation model proposes labels and annotators correct boundaries and rare classes, which cuts effort without removing human judgment on edge cases.
What makes LiDAR annotation services hard
- Sensor fusion. Labels should project cleanly into camera images, which requires accurate calibration. See our notes on depth camera calibration.
- Motion. A moving robot smears a scan, so ego-motion compensation has to happen before labeling.
- Multi-sweep context. Annotating accumulated sweeps reveals more structure but risks ghosting from moving objects.
- Sensor variety. Spinning LiDAR, solid-state LiDAR and depth cameras produce different density patterns, so guidelines must specify per-sensor handling.
Our guides to LiDAR and point cloud data collection and RGB-D data collection cover the capture side. Annotation quality starts there.
QA for 3D labels
Measure rather than eyeball:
- 3D IoU between annotators, or against gold standard boxes
- Per-class point accuracy for segmentation, plus boundary error
- Geometry checks for boxes below ground, impossible dimensions and orientation flips between frames
- Temporal consistency of IDs and sizes across frames
Roborax pairs automated geometric checks with senior review, and keeps every label linked to the raw sensor data and calibration so it can be re-projected or relabeled later. The same approach runs through our annotation and labeling work and our robotics data QA pipeline. To quantify consistency between reviewers, see our guide to inter-annotator agreement.
Frequently asked questions
Q: Boxes or segmentation: which do we need?
A: Boxes for detection and tracking. Segmentation when the robot must reason about surfaces or individual objects at the point level. Many programs start with boxes and add segmentation for the classes that matter most.
Q: How much does point density affect labeling?
A: A great deal. Sparse returns at range make boundaries ambiguous, so set per-range quality rules and an ignore class rather than forcing annotators to guess.
Q: Can labeled 3D data be reused across sensors?
A: Partly. Class definitions and geometry conventions transfer. Density-dependent rules and calibration do not, so store sensor metadata with every scan.
Robot perception data only helps when the labels match the sensors your robot ships with. If you are scoping point cloud annotation for a new platform, tell us what you are training and we will build a pilot around your sensors and ontology.
Related reading
- Warehouse and logistics solutions
- Domain Randomization for Manipulation: Which Parameters Actually Improve Transfer
External reference