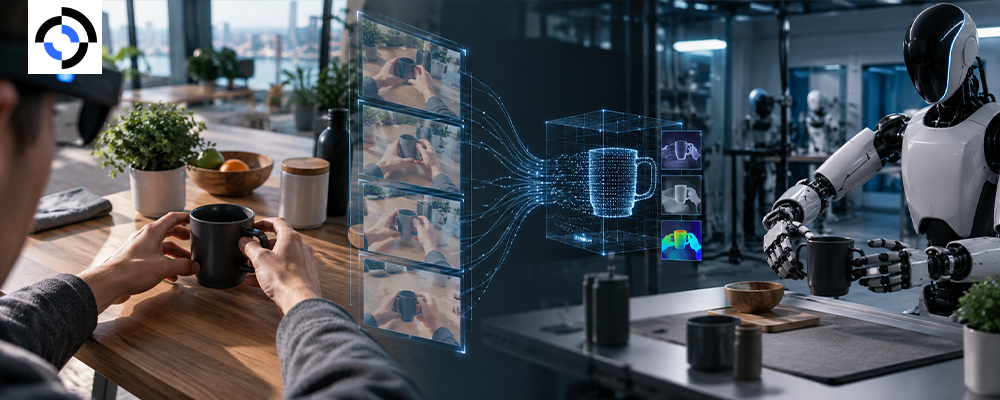
Vendors sell first-person video datasets by the hour. Robotics teams buy them expecting to train a policy, then discover the footage supports perception and nothing else. The mismatch is not dishonesty on either side. It is a disagreement about what makes a dataset usable.
This guide sets out the six properties that separate trainable data from footage, the three tiers of first-person capture, how to evaluate a dataset before you commit, and why hours is the wrong unit of measurement.
Not all first-person video is training data
There is a large amount of first-person footage in the world. Action cameras, body cams, smart glasses, gameplay recordings. Almost none of it can train a manipulation policy, and understanding why saves teams a great deal of wasted licensing spend.
The gap is not resolution or volume. It is that video alone tells you what happened but not what was done. A policy needs to learn a mapping from observation to action. Video gives you the observation half and nothing else.
The six properties that make a dataset usable
| Property | What it means | Without it |
|---|---|---|
| Action labels | What the actor did, frame by frame | Perception pretraining only; no policy learning |
| Temporal sync | All streams on one clock, drift under a few ms | Actions attach to the wrong frames |
| Calibration | Recorded intrinsics and extrinsics per session | No 3D grounding; no cross-session pooling |
| Task structure | Named tasks with phase boundaries | Cannot segment, cannot evaluate |
| Outcome labels | Success, partial, failure, with a reason | Cannot filter, cannot learn recovery |
| Diversity metadata | Objects, lighting, layout recorded per episode | Cannot audit coverage or diagnose bias |
A dataset with the first two is useful. A dataset with all six is trainable. Most public first-person video has neither of the first two, which is why it lands in the pretraining bucket rather than the fine-tuning bucket.
The three tiers of first-person video
Tier 1: passive footage
Someone wore a camera and lived their life. Enormous scene diversity, near-zero task structure, no action labels. Genuinely valuable for visual pretraining and scene understanding, and close to useless for manipulation on its own.
Tier 2: scripted human capture
A person performs defined tasks wearing a camera and hand tracking. Now you have task structure and approximate action labels. The remaining problem is the embodiment gap: human hands are not robot grippers, so actions need retargeting before a policy can use them.
Tier 3: robot-embodied capture
The demonstration was performed on the robot itself, through teleoperation. Action labels are exact because they were the commands. No retargeting, no viewpoint mismatch. Lowest throughput, highest value per episode.
Most serious programs use all three, weighted differently at each training stage. Our guide to egocentric data collection covers how the capture methods differ.
How to evaluate a dataset before you commit
- Ask for one complete episode, not a highlight reel. Everything you need to judge quality is in the raw record of a single episode, including the failures the reel omits.
- Check the timestamp integrity. Are streams independently timestamped, or is a constant rate assumed? Assumed rates hide dropped frames.
- Ask what fraction are failures. A dataset with no failures has been filtered, and the filtering removed the recovery behavior you need.
- Count unique object instances, not categories. “500 hours of kitchen tasks” with eleven objects is a narrow dataset wearing a large number.
- Look at the metadata schema. If it is thin, diversity cannot be audited and problems cannot be traced. See log design.
- Check licensing and consent provenance. Footage of real people in real homes carries obligations that do not disappear because the data was purchased.
Hours are the wrong unit
Datasets are sold in hours because hours are easy to count. Hours correlate poorly with training value.
Better units, in rough order of usefulness:
- Episodes with complete action labels – the actual trainable unit
- Unique object instances – the main driver of generalization
- Distinct scene configurations – lighting, layout, clutter combinations
- Failure and recovery episodes – usually the scarcest and most valuable slice
- Operator count – a proxy for behavioral diversity
A hundred hours from one kitchen with one operator is a smaller dataset than twenty hours across thirty homes, regardless of what the invoice says. The same principle drives the volume argument in how much humanoid training data you actually need.
Where first-person video genuinely wins
Nothing above says avoid it. Used correctly, large-scale first-person video is the cheapest way to give a model broad visual and physical common sense before you spend money on embodied capture.
The standard pattern is pretrain broad, fine-tune narrow: build representations from large passive corpora, then fine-tune on a much smaller set of robot-embodied demonstrations with exact action labels. That staging is why the embodied AI data flywheel compounds the way it does.
For what a properly labelled corpus produces downstream, our humanoid foundation model case study documents a 3x sample-efficiency result.
Frequently asked questions
Can I train a manipulation policy on public first-person video alone?
No. You can train perception and representations. Control requires action labels tied to a specific embodiment, which public corpora almost never carry.
How many hours of first-person video do I need?
Wrong question. Count labeled episodes, unique objects, and scene configurations instead. Teams that optimize for hours consistently end up with large, narrow datasets.
Does video resolution matter much?
Less than teams expect. Sync accuracy, calibration, and label quality matter far more. Many programs downsample resolution and still train well; none recover from bad timestamps.
Should we buy a dataset or collect our own?
Usually both, in that order. Buy for pretraining breadth, collect for embodiment-specific fine-tuning. Our build vs buy comparison works through the economics.
The dataset that looks largest on a spec sheet is rarely the one that trains best. If you are evaluating a first-person corpus or planning your own capture, send us the spec and we will tell you what it can and cannot support.